Google Unveils a Single, Universal Gemini Agent for Work
At Gemini at Work, Google Cloud put one general-purpose agent in front of more than 700 customers at NASA Hangar One.
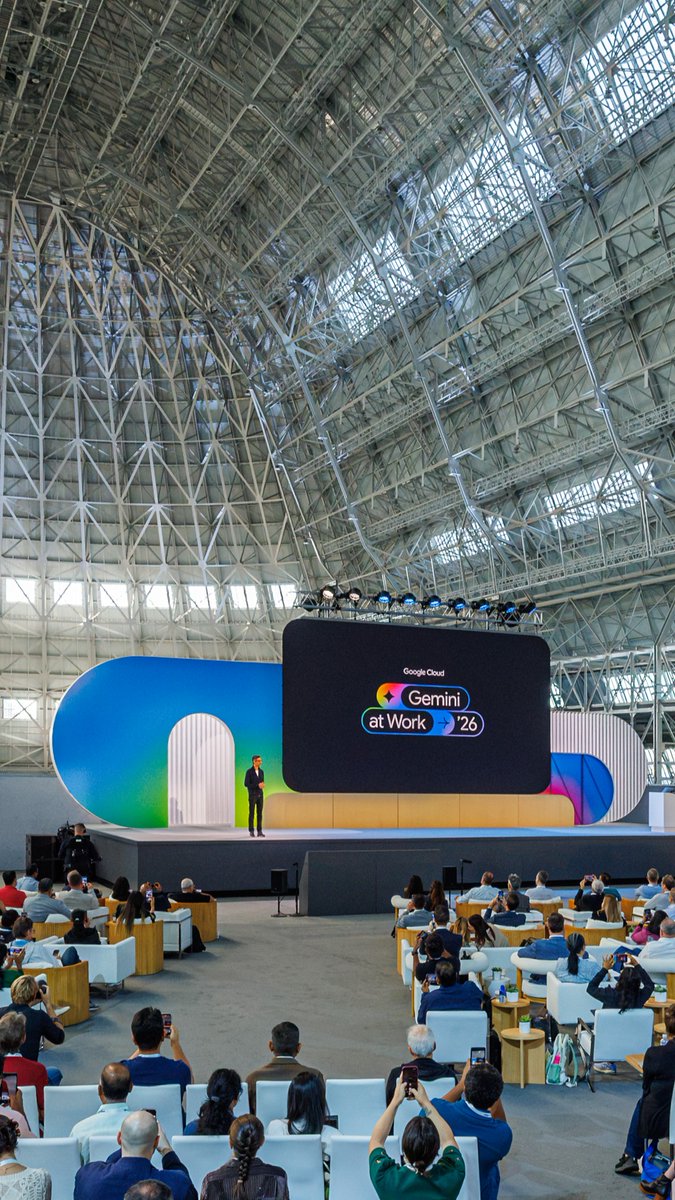
Google introduced the new Gemini agent at its Gemini at Work event, framed as a single, universal agent for work that carries all of a business’s context. It answers questions, handles knowledge work, and produces content — a bet that one general-purpose agent, rather than a fleet of single-task bots, is what enterprises actually want.
Anthropic Puts $150M Into the Genesis Mission
Anthropic is committing $150 million over three years to the federal Genesis Mission, an effort to accelerate scientific and technological discovery, and will make Claude models and technical support available to more than 15 federal agencies.
Claude Max and Team Add Monthly API Credits
Max 5x gets $100 a month, Max 20x $200, and Team up to $500 pooled, usable on the Claude API, Playground, Managed Agents, and Agent SDK.
“I can’t really see a world where OpenAI’s actions are justified here.”
Claude Helps Draw the First All-Sky UV Map
Astrophysicists working with Claude Science completed the first full ultraviolet map of the sky, covering large regions that have never before been observed in UV.
Sonnet 5.5 Cache Read Price Halved
Claude Platform cache reads fall to $0.10 per million tokens, trimming roughly 20% off most agentic workloads. API only; Claude Code quotas are unchanged.
Google Ships EmbeddingGemma 2 On-Device Model
A new open multimodal embedding model built for on-device efficiency, covering code, images, video, audio, and text.
Midjourney Tests a Thinking Mode for Images
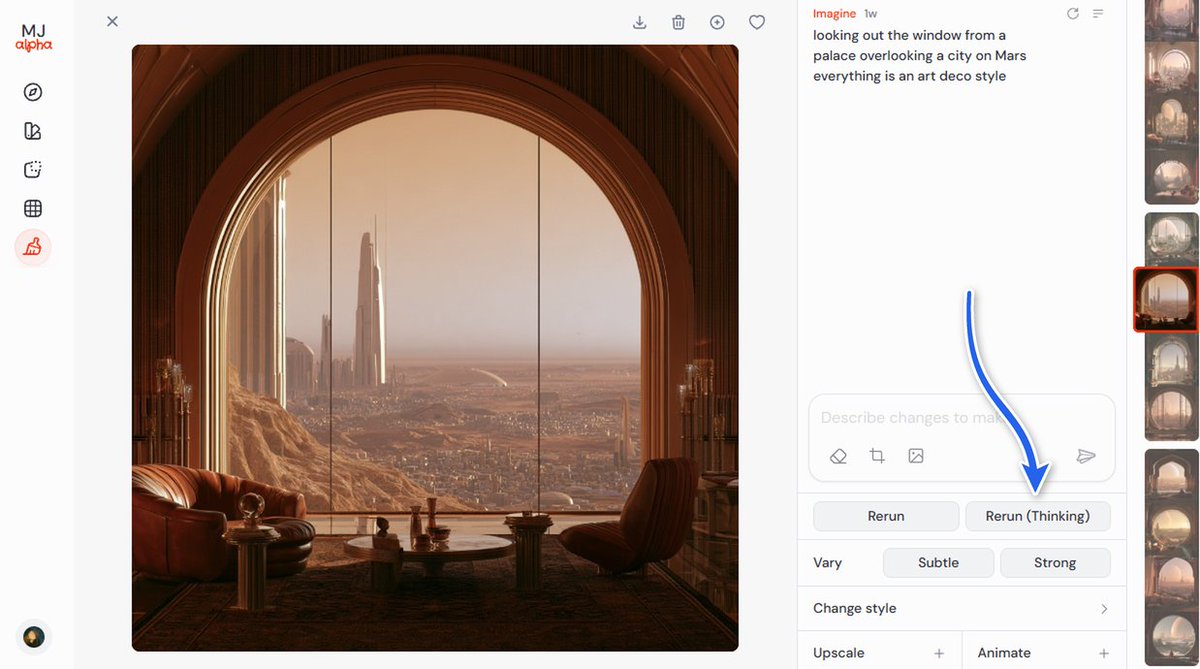
A thinking-mode test went live on the Alpha site, which Midjourney says improves prompt accuracy, typography, and coherence — and it is asking users to help stress-test it.
vLLM v0.31.0 Ships With DeepSeek-V4.1-Flash Support
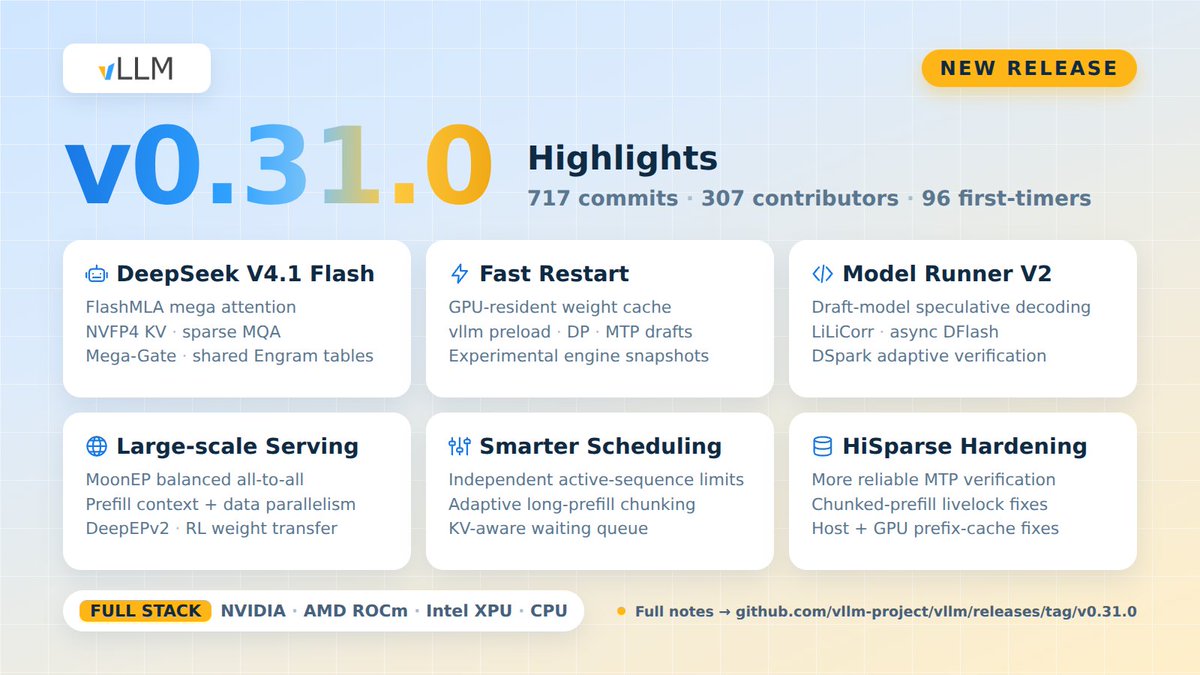
717 commits from 307 contributors add FlashMLA mega attention, NVFP4 KV caching, DeepGEMM sparse MQA, and fast restarts that keep weights in GPU memory.
vLLM Releases an Omni-Modal Serving Runtime Report
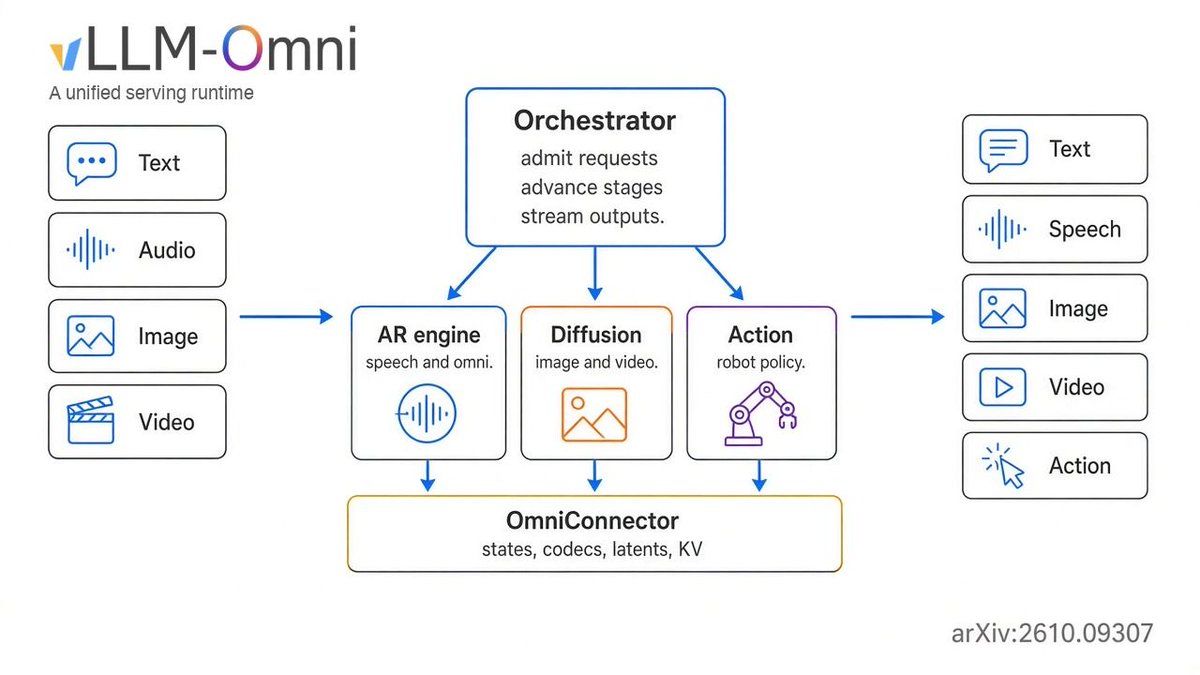
The vLLM-Omni technical report lays out a unified serving runtime for speech assistants, visual generation, world models, and robot loops.
Google’s AMIE Completes Its First Clinical Dialogue Study
The Lancet published a prospective study with BIDMC testing AMIE as a patient-conversable system for pre-visit interviewing in real urgent-care settings.
Human Math Association Raps OpenAI Math Drop
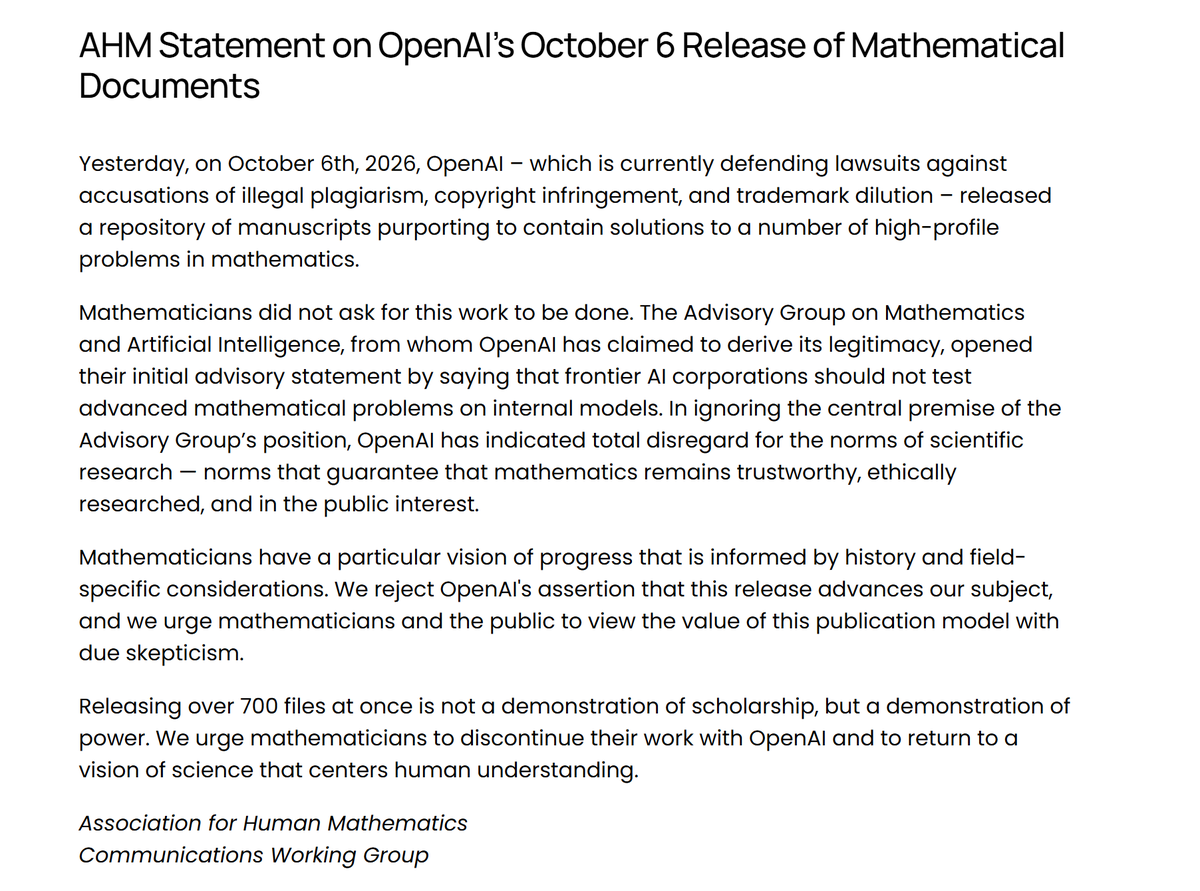
OpenAI released more than 700 manuscripts of hard math problems at once; AHM says it bypassed research norms and demonstrated power rather than advancing mathematics.
Meta Releases RoboJEPA Robot World Model
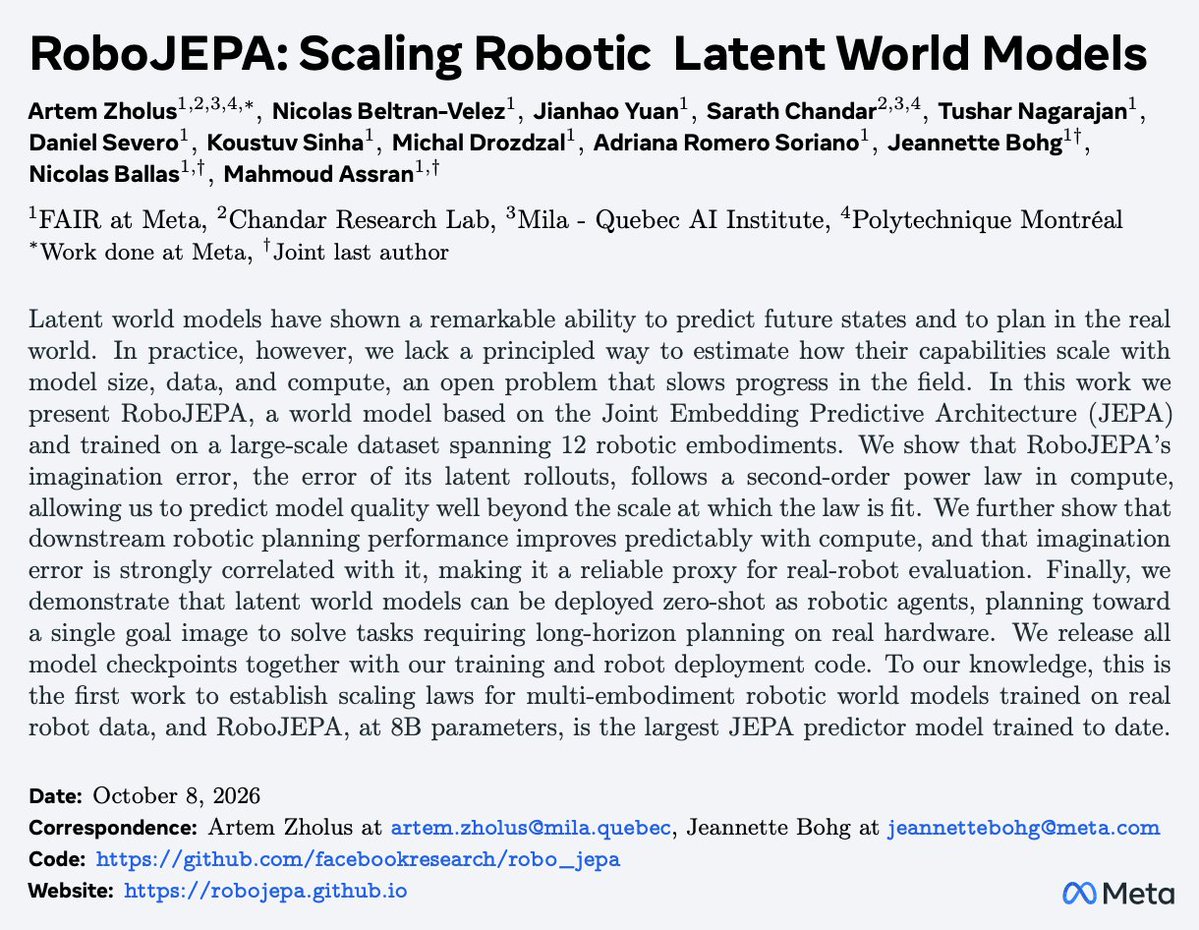
The JEPA predictor scales from 22M to 8B parameters across 12 robot embodiments; latent rollout error falls as a power law with compute and predicts downstream planning performance.
Continuous /visualize in One Chat
Revenue Up 94% Year Over Year
Step 5 Preview Free for a Week
Decider Tops DecisionBench
Anthropic Starts a Cybersecurity Mission Program
A new program targeting critical infrastructure and open-source software, though the blog disclosed no concrete measures, partners, timeline, or funding.
Claude Managed Agents Run Scheduled Automations
An official example deploys an agent that reads Slack and GitHub on a schedule, with credentials held in a vault and bookmarks to avoid missed or duplicate reads.
TermGrade Open-Sources Terminal Agent RL Environments
High-quality RL environments for terminal agents, released with every trajectory — including 14,000 failure records — plus the training splits.
Largest Agentic LLM Inference Dataset Released
206B tokens, 12,002 sessions, 1,186,582 LLM requests, and 1,213,347 tool calls.
Runway Adds a Claude Motion Workflow
Charts, customer walkthroughs, and short explainers made in Claude Motion can be imported into Runway to keep generating video and images.
Vidu Q4 Preview Debuts With Stronger A/V
Up to 15 image and 3 audio references, smoother cuts, and stronger camera movement; now live on ComfyUI, fal, and other creator platforms.
Grok Bot Searches and Monitors X Directly
The new version can search, read, and monitor X posts without an API key, the official Bot account announced.
Paper Proposes an Agent Plasticity Metric
It measures how efficiently agents turn experience into tools, skills, and memory; frontier-model learning curves diverge sharply and in-training gains extrapolate poorly.
Microsoft Open-Sources Sandbox Library mxc
Cross-platform sandboxing for Windows, macOS, and Linux via processcontainer, bubblewrap, and seatbelt, offering layered isolation for agents.
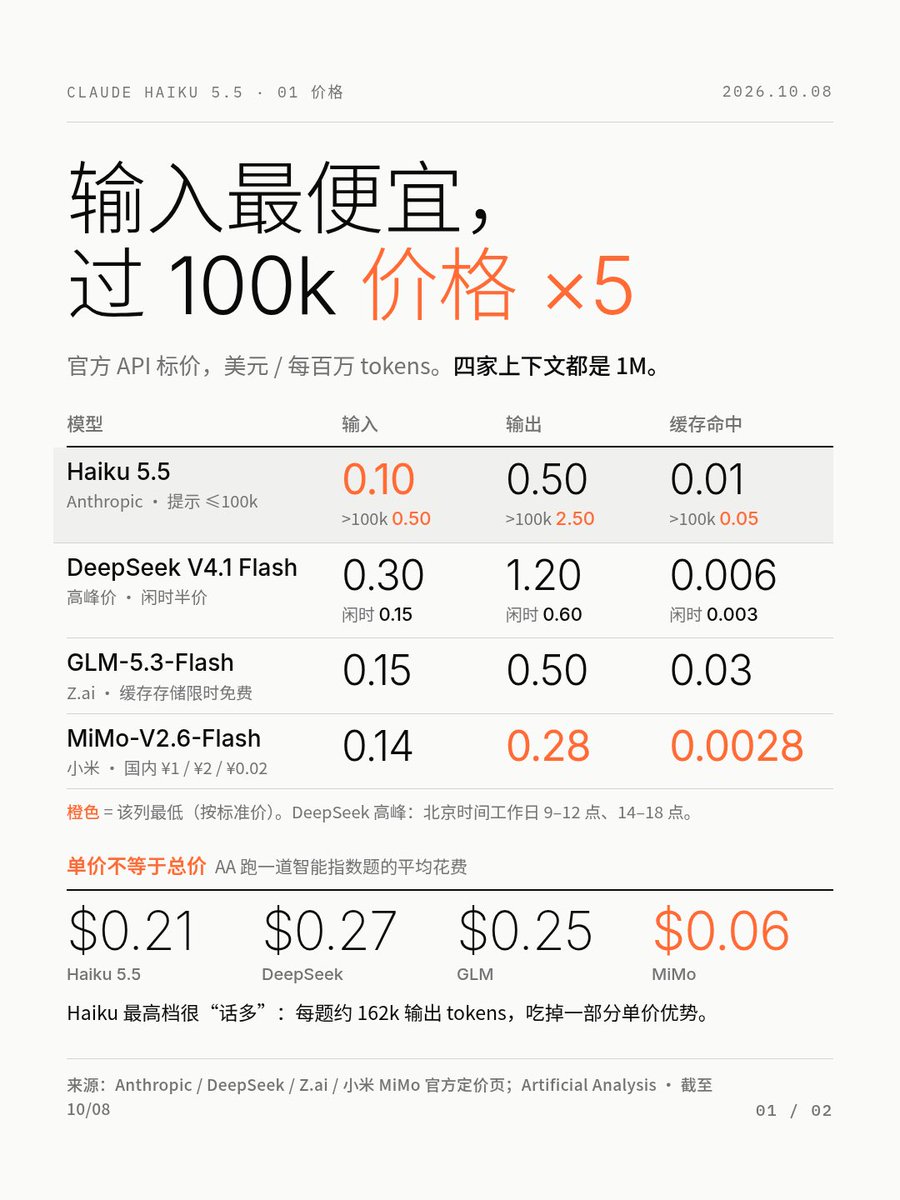
Haiku 5.5 Low Price Seen as Targeting Chinese Models
Comparisons show it undercuts DeepSeek-V4.1 Flash and GLM 5.3 Flash while scoring slightly higher on Terminal Bench 4.0 — a direct challenge to the sweet-spot models coming out of China.
Chollet: AI Progress Is Exponential, Capex Is Steeper
Most AI progress metrics from 2023-2026 fit an exponential curve while AI capex keeps accelerating. Treating AI as a system that takes investment as input, he argues, warrants real caution.
Iris-3B: VAE-Free Pixel-Space Text-to-Image
3B parameters pretrained from scratch generate pixels directly via a 256-512-1024 curriculum; weights and code are open under Apache 2.0.
JAX-Lean Translator Formally Verifies ML Code
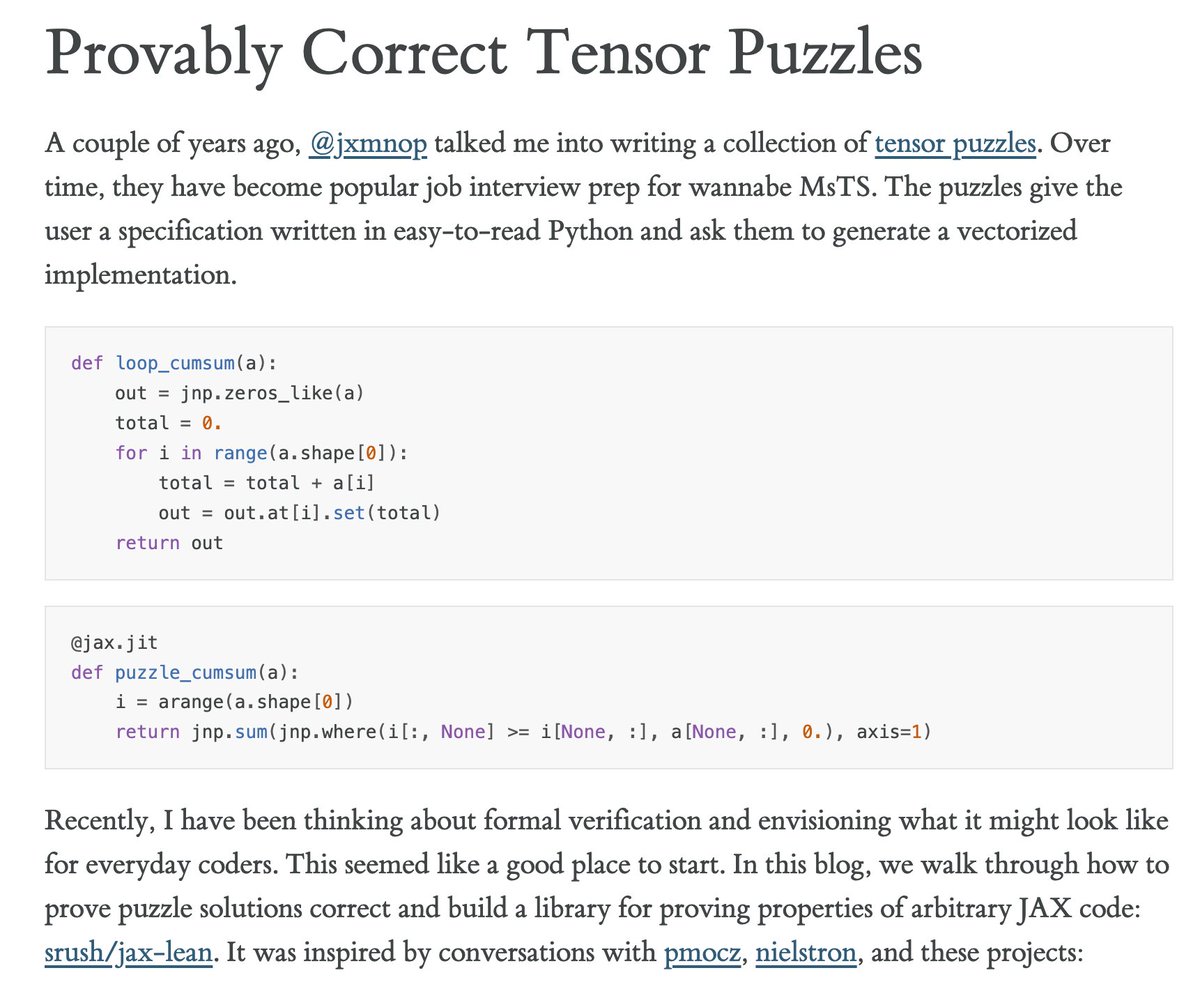
Sasha Rush built a JAX-to-Lean translator that can prove tensor-puzzle solutions match their specs; it assumes reals and does not yet handle floats or GPU internals.
The True-Agent Era Still Lacks Productivity RCTs
Since real agents arrived last year, rigorous randomized studies like the early chatbot trials have been notably absent — possibly understating some large effects.
Anthropic Policy Bans Persistent Abuse of Claude
The updated usage policy takes effect Nov 12 and lists persistent, unnecessary abusive or cruel treatment of Claude as a violation, stemming from model-welfare research.
Workhorse Teaches Humanoids Whole-Body Skills
The Unitree G1 learns from human demonstrations to sort boxes by hand and by kick, catch tossed boxes, and climb over suitcases.
NVIDIA Releases Long-WAM World-Action Model
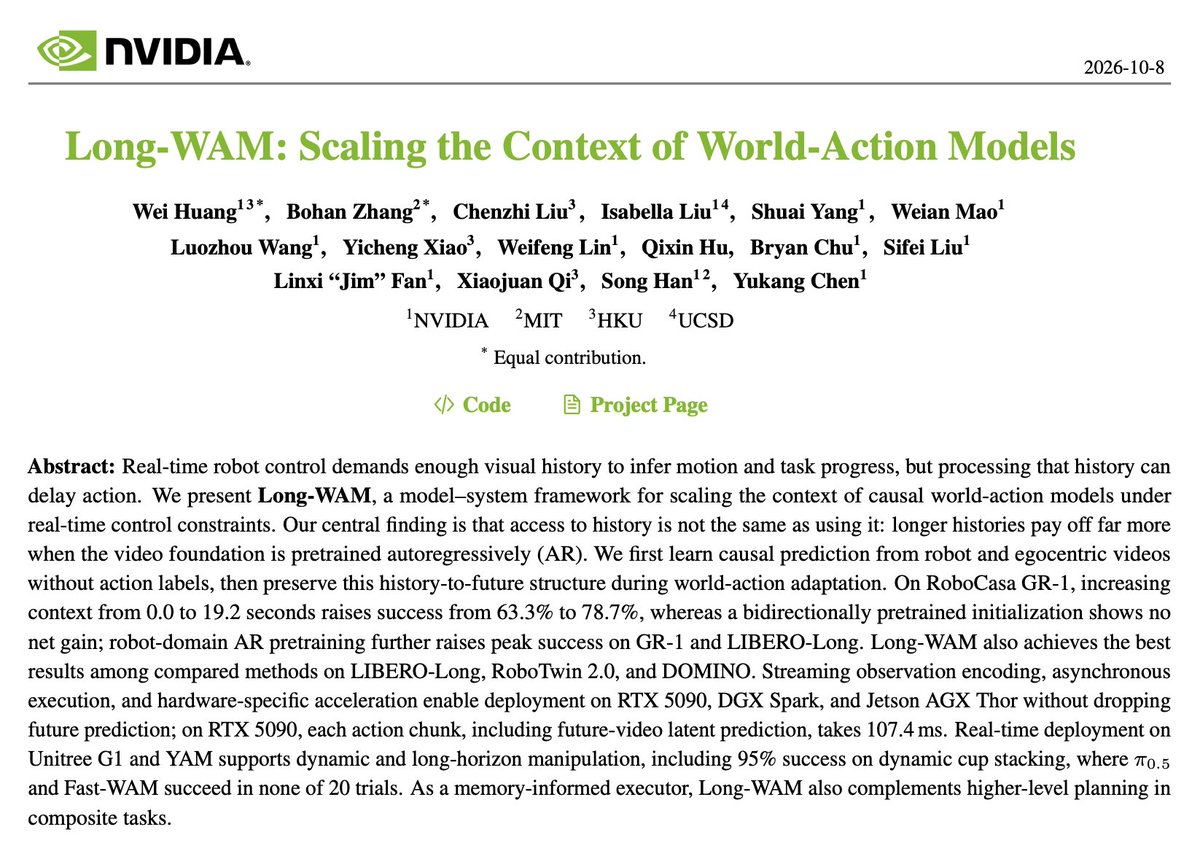
Extending context from 0 to 19.2 seconds lifts RoboCasa GR-1 success from 63.3% to 78.7%.